AI & Tools
Claude Opus 5.5 Checked: Fable Level at an Opus Price?
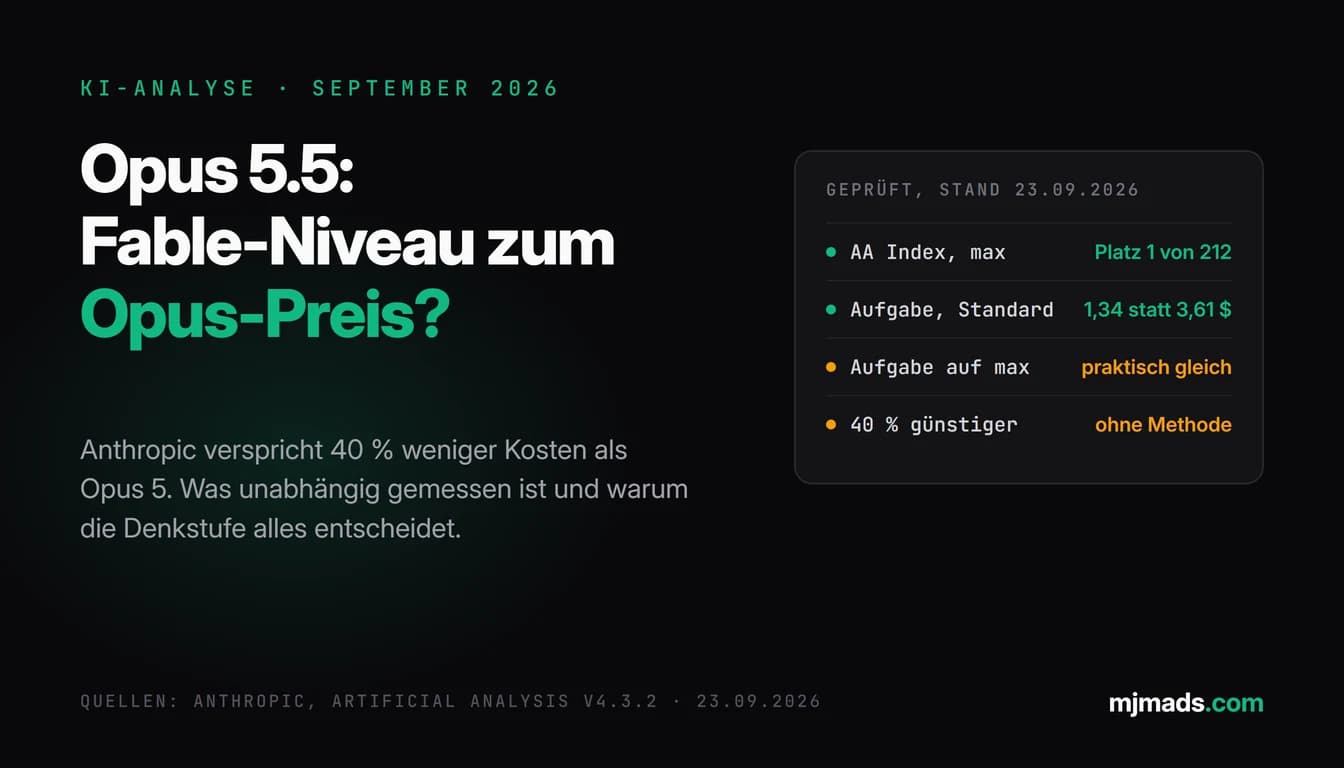
Anthropic promises Fable-level results at 40 percent lower cost than Opus 5. What is independently measured, what a task costs, where the catch is.
25 min read
Mijo Jurisic
Read more5 articles
Anthropic promises Fable-level results at 40 percent lower cost than Opus 5. What is independently measured, what a task costs, where the catch is.
Anthropic leads nine benchmarks, independent runs are much closer. What Claude Fable 5.1 delivers, what it costs and when Opus 5 is enough.
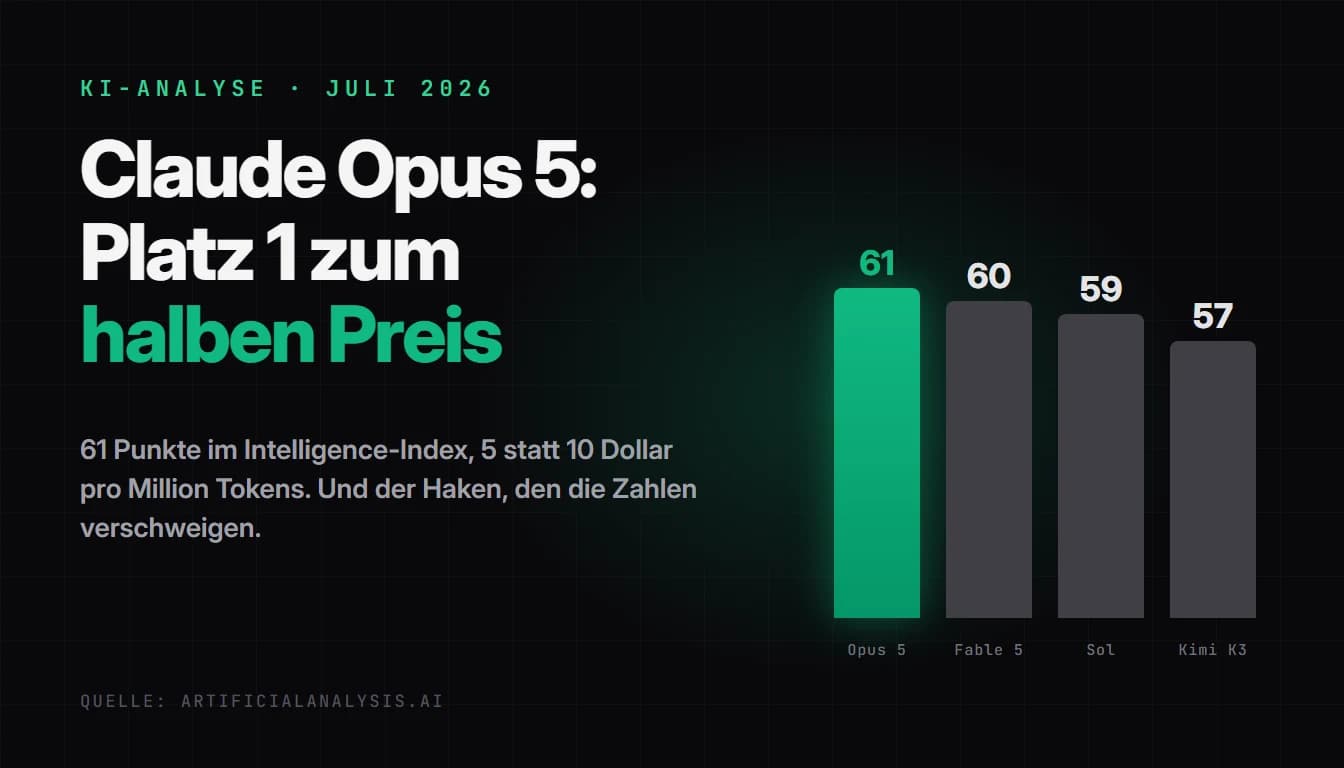
Claude Opus 5 benchmarked: first place in the Intelligence Index with 61 points, half the Fable 5 price and the cost paradox of verbosity.
OpenAI's GPT-5.6 line (Luna, Terra, Sol) in a benchmark check and the METR cheating findings: why strong numbers and reward hacking show up together.
Kimi K3 by Moonshot AI benchmarked: the largest open model, ranked 2nd to 4th against Fable 5 and GPT-5.6 Sol, best price-performance ratio.