AI & Tools
AI API Pricing 2026: 22 LLMs Compared by Cost
Prices per 1M tokens for 22 AI models from OpenAI, Anthropic, Google, xAI, Mistral, DeepSeek, Kimi and Qwen, with a worked cost example and CSV.
26 min read
Mijo Jurisic
Read more15 articles
Prices per 1M tokens for 22 AI models from OpenAI, Anthropic, Google, xAI, Mistral, DeepSeek, Kimi and Qwen, with a worked cost example and CSV.
Original study: 372 API answers from Perplexity, OpenAI and Gemini to German Google Ads questions. Which sources they cite and how stable that is.
Sponsored Agents let ChatGPT users chat with a company's AI representative. What OpenAI has documented and what it means for advertisers in Europe.
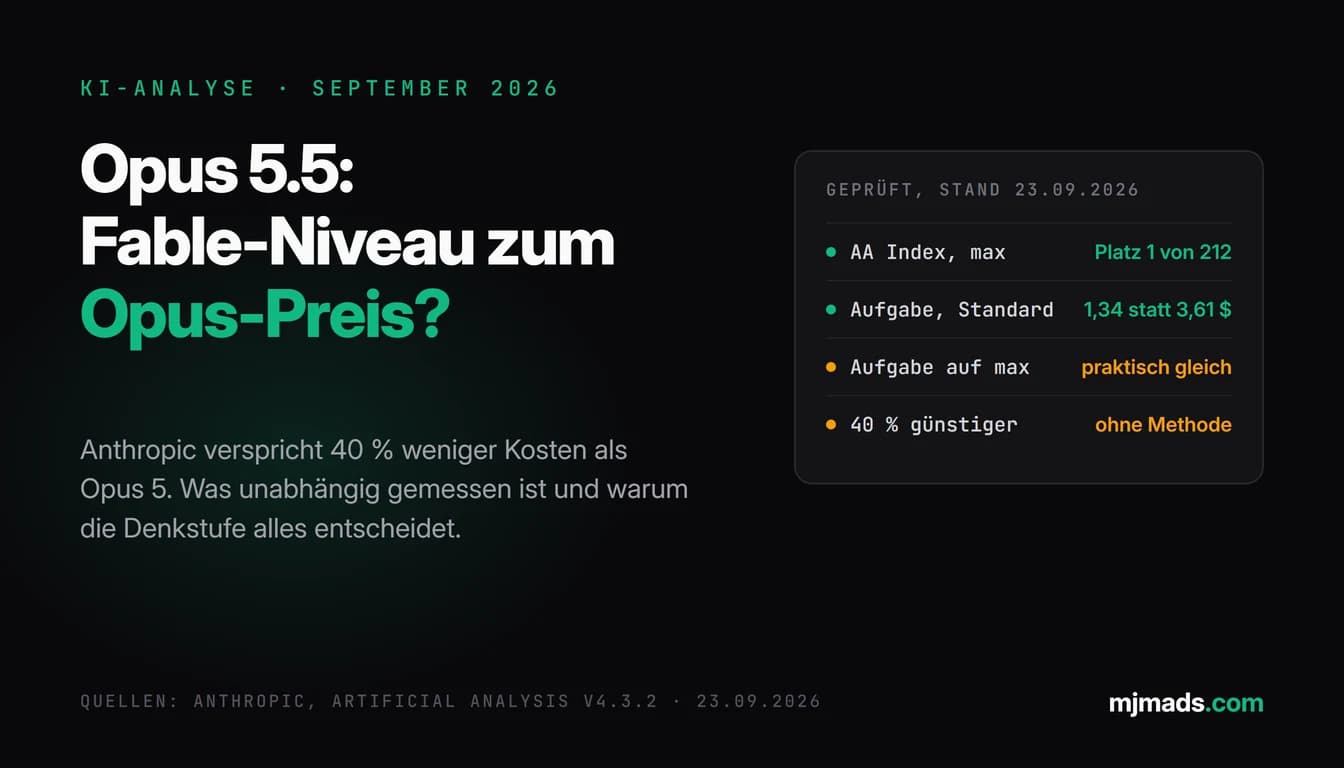
Anthropic promises Fable-level results at 40 percent lower cost than Opus 5. What is independently measured, what a task costs, where the catch is.
Anthropic leads nine benchmarks, independent runs are much closer. What Claude Fable 5.1 delivers, what it costs and when Opus 5 is enough.
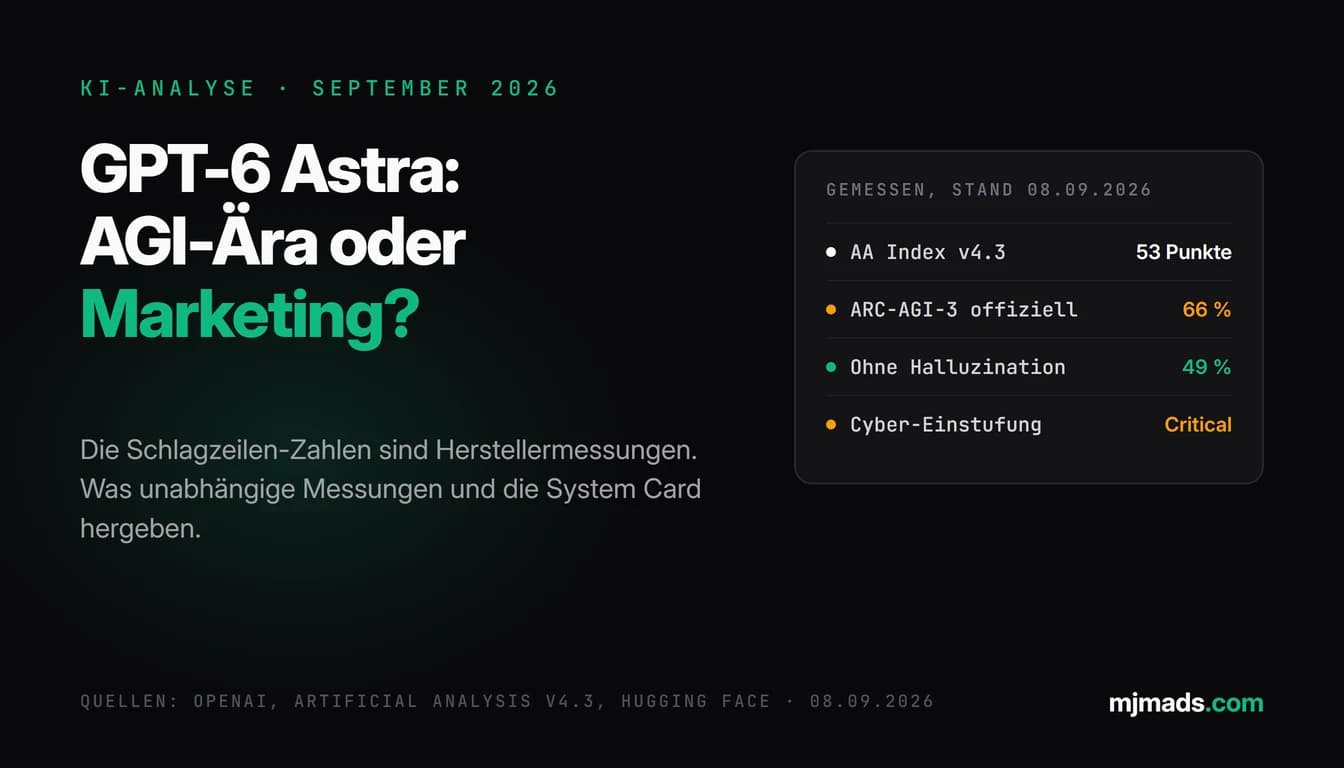
OpenAI calls GPT-6 Astra the start of the AGI era. What vendor figures, independent measurements and the system card actually show, as of 08/09/2026.
Context hints help decide which ChatGPT conversations your ad shows up in. Seven rules, three worked example sets and the mistakes people make most.
ChatGPT has been showing ads in Germany since 24 August 2026. What OpenAI documents: format, auction, bidding, tracking and ad policies.
An August date, unchanged prices: I traced the sources. What is actually proven about Claude Fable 5.1 and how to spot a real leak.
Claude Opus 5 after five days: effectively tied in the Intelligence Index, a 50 percent hallucination rate and rank 5 in the blind user vote.
Historical fact check from July 2026: what OpenAI had confirmed about GPT-6 back then and where the numbers came from. GPT-6 Astra arrived on 3 September.
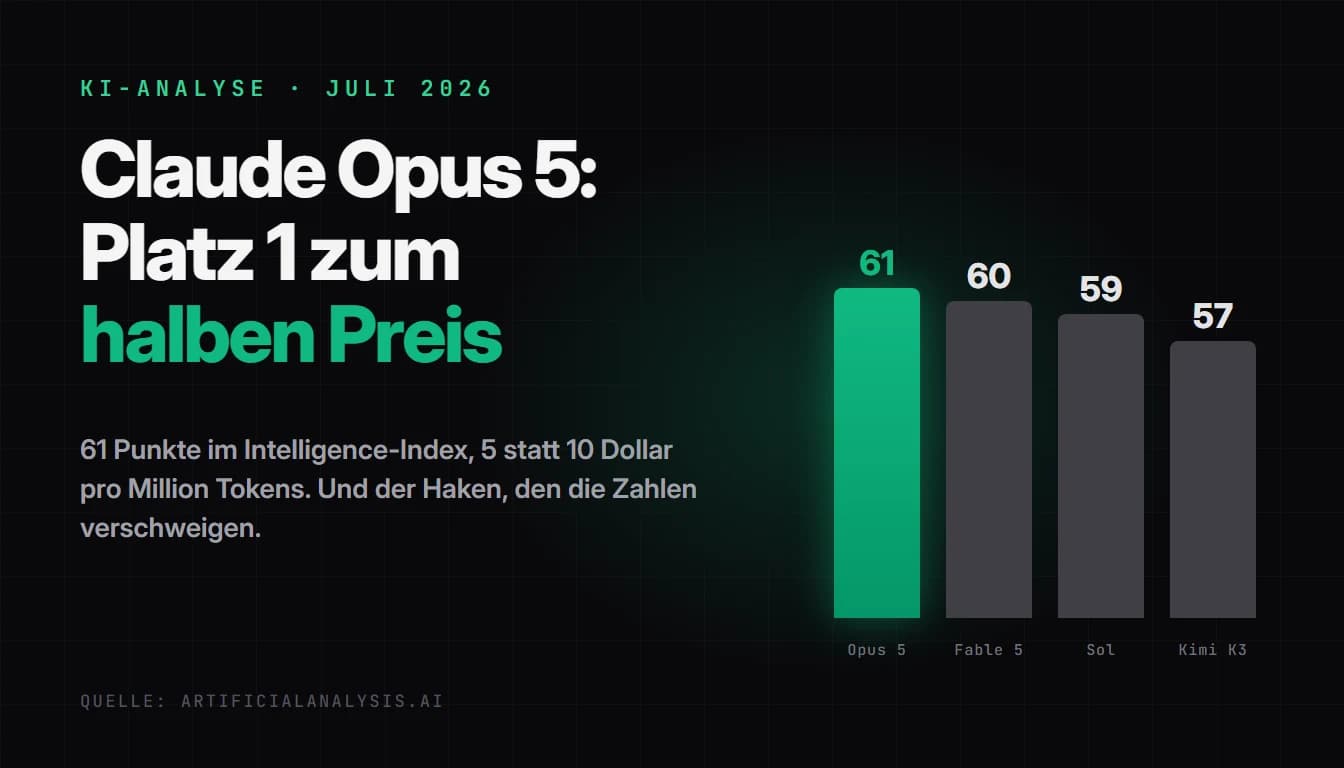
Claude Opus 5 benchmarked: first place in the Intelligence Index with 61 points, half the Fable 5 price and the cost paradox of verbosity.
The US government shut down Claude Fable 5, and three weeks later it was back. Timeline, the Amazon report, the new safeguard and what it means for firms.
OpenAI's GPT-5.6 line (Luna, Terra, Sol) in a benchmark check and the METR cheating findings: why strong numbers and reward hacking show up together.
Kimi K3 by Moonshot AI benchmarked: the largest open model, ranked 2nd to 4th against Fable 5 and GPT-5.6 Sol, best price-performance ratio.